

Use RSS when a publisher needs to syndicate new items and a consumer can poll for updates. Use a REST API when an application knows the resource and operation it needs. Use MCP when an AI client should discover a set of tools and choose which operation fits the user’s request. Many useful agent systems combine all three.
The formats are not competitors in the usual sense. RSS is often an input, REST is an application interface, and MCP is an agent-facing tool interface. This guide compares the jobs, shows three working architectures, and uses Sparkfeed’s live demo to verify the examples.
What is the difference between RSS, an API, and MCP?
RSS is a standardized XML feed for publishing a sequence of items. A REST API exposes resources and operations over HTTP. MCP lets an AI client discover and call tools through a standard protocol.
| Interface | Core job | Who chooses the operation? | Typical authentication | Best fit |
|---|---|---|---|---|
| RSS or Atom | Publish and subscribe to new items | The consuming application | Often public, sometimes tokenized | Blogs, news, releases, podcasts, changelogs |
| REST API | Read or change known resources | Application code | API key, OAuth, session, or signed request | Integrations, dashboards, scheduled jobs |
| MCP | Expose tools and context to an AI client | The model or client, within policy | OAuth or bearer access token, depending on server | Interactive agents and AI-assisted workflows |
The RSS 2.0 specification defines RSS as a web-content syndication format. RFC 4287 standardizes Atom as an XML feed format. The MCP transport specification defines standard input and output for local servers and Streamable HTTP for remote servers.
When should you use RSS?
Use RSS when the main question is “What has been published since the last check?” It is simple, cacheable, portable, and supported by many publishers and readers.
An RSS item usually contains a title, link, date, identifier, and description. Atom uses a similar model with standardized entries and metadata. The consumer polls the feed, compares identifiers, and stores new items.
RSS is especially good for:
- News and blog subscriptions
- Product release notes and changelogs
- Podcast episodes
- Public status and announcement streams
- Moving subscriptions between readers with OPML
RSS is not a general query language. A feed usually cannot answer “show unread security articles from the last seven days in this workspace” unless the reader builds that query over stored items. It also does not define a standard way to favorite an article, create a folder, or fetch a cleaned full-text version.
The guide to turning any website into an RSS feed covers native feeds, no-RSS pages, and OPML portability.
When should you use a REST API?
Use a REST API when code knows the endpoint, method, parameters, and response it needs. REST is predictable for scheduled jobs, product integrations, data exports, and application backends.
For example, Sparkfeed’s API exposes a read-only demo endpoint for recent articles:
curl -s \
  'https://demo.sparkfeed.dev/api/v1/articles?since=7d&limit=2' \
  -H 'Authorization: Bearer sfk_demo_public'
This command was tested on August 31, 2026. It returned 200 OK, an articles array with two compact records, and a next_cursor for pagination. Each record included its source, folder, publication date, snippet, reading flags, and whether full text was available.
Sparkfeed publishes its current OpenAPI 3.1 document. The REST interface includes workspace information, folders, feeds, article search, individual article reads, source discovery, and scoped write operations.
REST is a strong fit when:
- A scheduled job has a fixed query
- A product needs typed integration code
- Operations teams want predictable logs and retries
- A service should not let a model decide which action to call
- An OpenAPI document will generate clients or validation
The application must still handle authentication, pagination, rate limits, retries, and response-version changes.
When should you use MCP?
Use MCP when an AI client should inspect available tools and choose a tool based on the user’s question. The server describes each tool, its inputs, and behavioral annotations. The client performs initialization and tool discovery before making calls.
With Sparkfeed, an agent can discover tools such as list_folders, search_articles, and get_article. A typical interaction is:
- List folders to understand the workspace.
- Search recent articles within the relevant folder.
- Inspect compact results.
- Fetch the full text of one selected article.
The user can ask “What changed in our AI research sources this week?” without knowing an HTTP route or query parameter. The client maps that intent to the available tools.
MCP is a strong fit when:
- A model needs tool discovery
- Users ask varied natural-language questions
- One client connects to many independent tool servers
- Tool descriptions and read/write annotations should guide the client
- The same workflow may require several dependent calls
MCP does not remove the need for authorization or application rules. The server remains responsible for scopes, data isolation, limits, and validating every tool input.
How do RSS, REST, and MCP fit together?
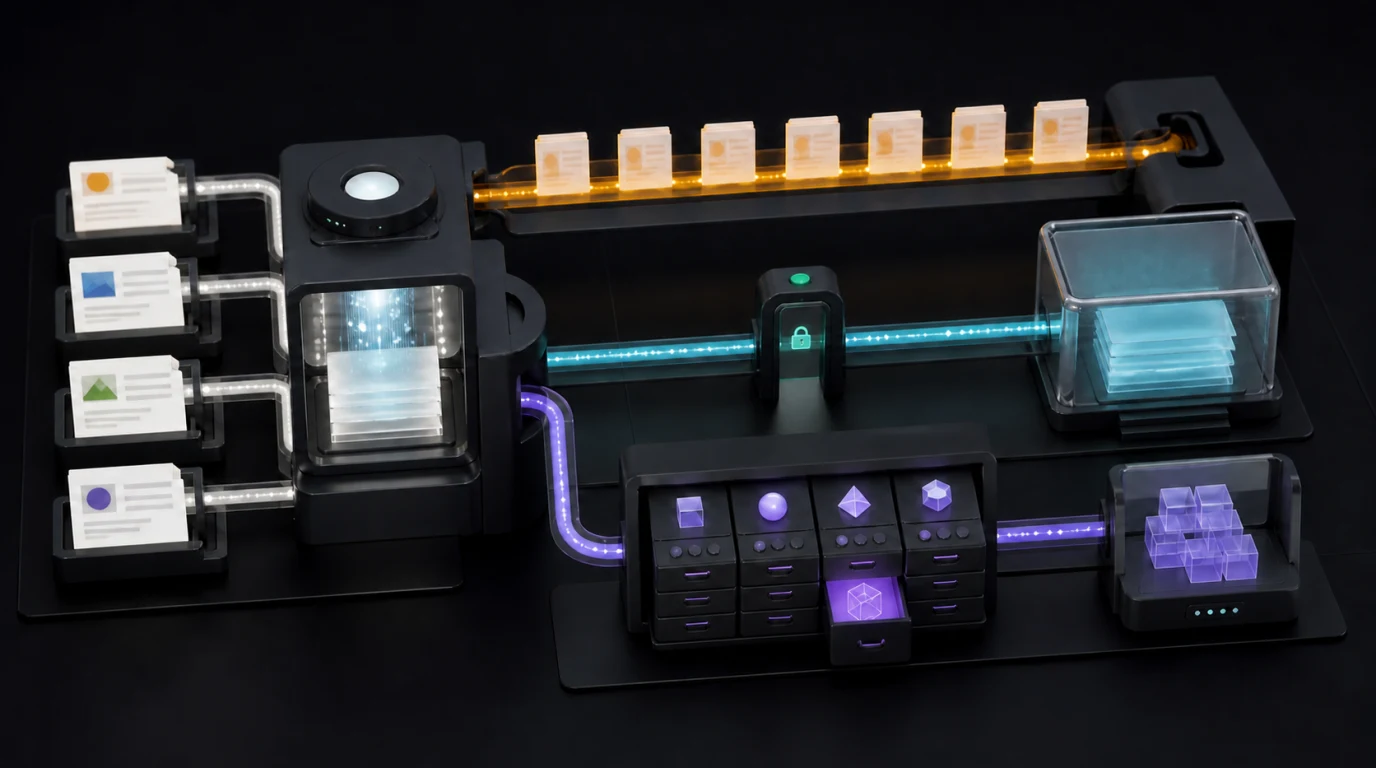
The most useful architecture treats them as layers. RSS and watched pages bring information in. REST and MCP provide different ways to query or act on the stored result.
This layered design prevents each integration from rebuilding collection, deduplication, and full-text retrieval. It also lets the team choose the safer interface for each job.
Three validated architecture patterns
Pattern 1: Direct feed ingestion
Use this when the consuming service needs a chronological stream and the publishers already provide feeds.
publisher feeds -> scheduled poller -> parser -> database -> applicationThe poller stores each item’s identifier, link, date, and content. It uses conditional requests where available and retries failed feeds without blocking the rest.
This pattern has the fewest moving parts. It becomes less attractive when many important sources lack feeds or the application needs team state, full-text extraction, cross-source search, and access controls.
Pattern 2: REST integration over a source workspace
Use this when a service has a known report or automation.
RSS and watched pages -> Sparkfeed workspace -> REST API -> report jobA weekly job can call /api/v1/articles with a folder, date range, and cursor. It can then fetch selected full articles from /api/v1/articles/{id}. The job owns the schedule, retries, output format, and destination.
REST keeps control in application code. That is valuable when the operation sends data somewhere else or affects shared workspace state.
Pattern 3: MCP access for an AI client
Use this when users ask varied questions and the client should choose among search, list, and read tools.
RSS and watched pages -> Sparkfeed workspace -> MCP server -> AI clientThe client connects to /api/mcp over Streamable HTTP and supplies a bearer key. It discovers only the tools allowed by that key’s scopes. A read-only key can search and read without exposing write tools.
The open-source MCP server guide includes the exact Claude Code and JSON client configuration.
A research team can apply the same interface choice to the workflow in how to gather competitive intelligence.
How do authentication and scopes differ?
RSS is often public, but private feeds may use unguessable URLs, HTTP authentication, or signed tokens. REST APIs commonly use API keys or OAuth. MCP authorization depends on the server and deployment.
Sparkfeed uses workspace-scoped bearer keys for both REST and MCP. The same key identifies one workspace and carries explicit scopes.
| Scope | REST examples | MCP tools |
|---|---|---|
workspace:read |
/workspace, /folders, /feeds |
get_workspace_info, list_folders, list_feeds |
articles:read |
/articles, /articles/{id} |
search_articles, get_article |
articles:write |
/articles/read, /articles/favorite |
mark_read, set_favorite |
feeds:write |
/feeds, /folders, feed moves |
add_feed, create_folder, move_feed |
MCP also requires the mcp scope to access its endpoint. Tools without a granted scope are not registered for that client.
Use a separate key per integration. A daily report should not share a key with an interactive agent, and a read-only summarizer should not receive write scopes.
Self-hosters should also account for database, backup, email, TLS, and provider operations. The self-hosted feed-reader guide covers that boundary.
How do freshness and pagination work?
RSS freshness depends on publisher updates and polling frequency. REST and MCP freshness depend on the collector behind them. Neither interface can return an item the source workspace has not fetched yet.
Sparkfeed’s article search accepts ISO dates or relative values such as 7d and 24h. REST returns next_cursor when another page exists. MCP returns the same cursor through search_articles. Full articles can also return a next_offset when content exceeds the requested character limit.
Cursor pagination is preferable to guessing page numbers in a changing timeline. The next request continues from a stable item boundary, even if newer articles arrive between calls.
What happens when requests fail?
Failure handling belongs in the integration, regardless of interface.
| Failure | Recommended response |
|---|---|
| Feed returns invalid XML | Record the source error, retry later, and keep other feeds running |
REST returns 401 |
Check the bearer scheme, key value, expiry, and revocation |
REST or MCP returns 403 |
Check plan access and required scope |
Endpoint returns 429 |
Respect Retry-After or retry_after_ms and use backoff |
| Article full text is unavailable | Use the stored RSS summary and preserve the lower source-quality label |
| MCP client starts OAuth unexpectedly | Verify the static bearer header before debugging discovery |
| Tool result is truncated | Continue with next_cursor or next_offset |
Never convert an authentication failure into an OAuth registration attempt unless the server actually advertises an authorization server.
How should agent security change the interface choice?
Use deterministic REST code for high-consequence actions unless the agent workflow has strong policy checks and human approval. Use read-only MCP tools for research wherever possible.
Web content remains untrusted no matter how it enters the system. OWASP identifies indirect prompt injection as a risk when models process websites and files. A curated feed improves provenance but does not make embedded instructions safe.
If the main input is a set of changing product or policy pages, the self-hosted website-change guide explains how those pages can enter the collection.
Useful controls include read-only keys, source provenance, narrow tools, input validation, action logging, and human approval for external side effects.
Is it legal to use RSS feeds?
RSS is a format, not a blanket license to republish content. A publisher making a feed available permits technical access to that feed, but copyright, database rights, contract terms, trademarks, privacy, and jurisdiction still apply.
Use feeds to follow and link to sources. Do not assume that a public feed grants the right to republish full articles, remove attribution, or sell a copied archive. Organizations with redistribution use cases should review each publisher’s terms and seek legal advice.
Sources and further reading
- RSS Advisory Board: RSS 2.0 Specification
- RFC Editor: The Atom Syndication Format, RFC 4287
- Model Context Protocol: Transports
- Model Context Protocol: Publishing remote servers
- OWASP: LLM01 Prompt Injection
- Sparkfeed OpenAPI document
- Sparkfeed MCP documentation
- Sparkfeed source code
Frequently Asked Questions
What does an RSS API do?
An RSS API usually discovers feeds, parses RSS or Atom, normalizes items, or exposes stored feed data as JSON. Some products also add webhooks, full-text extraction, search, and source management.
What is the difference between an RSS feed and an API?
An RSS feed publishes a chronological collection of items in a standard XML format. An API can expose any resources and operations its designer chooses, including queries and writes that RSS does not define.
Is an RSS feed free?
Many public RSS feeds are free to access. The infrastructure used to collect, store, search, or redistribute them may have costs. A publisher can also place a feed behind authentication or other access terms.
Can I create my own RSS feed?
Yes. A publisher can generate RSS 2.0 or Atom XML from a content system. A separate service can also monitor a supported page and generate feed items when the page adds new entries.
Is MCP better than a REST API?
MCP is better for model-driven tool discovery and interactive agent workflows. REST is better when application code already knows the operation and should control it deterministically. Many systems expose both.
Should an AI agent use RSS directly?
Direct RSS is enough when the agent only needs a small chronological stream. Use a stored workspace and API when it needs cross-source search, folders, full text, reading state, access controls, or reproducible historical queries.
